by Amit Shekhar · 1 September 2026
Decoding EAGLE
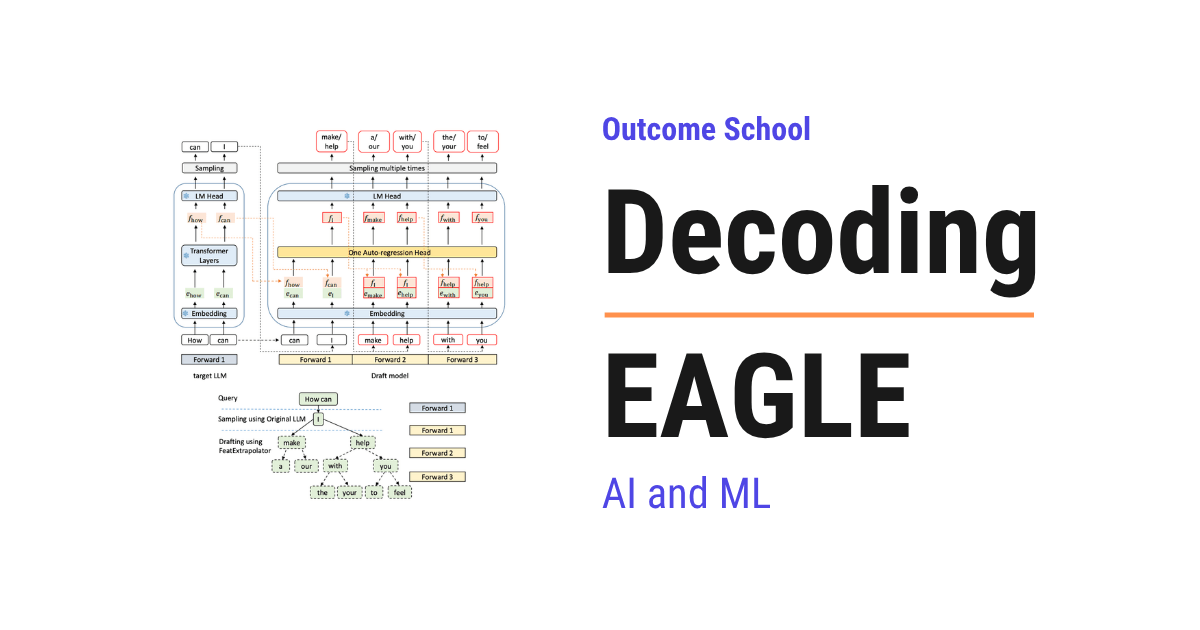
EAGLE, a state-of-the-art way to speed up language model generation by drafting tokens at the feature level instead of the token level.
Read on Outcome School ↗then come back to lock it in
Before you read, guessHow does the accuracy of token predictions impact the performance gains in speculative decoding?
Ten seconds, a guess, then read — a wrong guess still makes the answer stick.
What this article covers
- What is EAGLE
- A quick recap of speculative decoding
- The problem with token-level drafting
- The big idea: draft at the feature level
- Resolving the uncertainty by feeding back the token
- The math behind the speedup with small numbers
- EAGLE-2 and dynamic draft trees
- How EAGLE lives on today
The article lives on outcomeschool.com. Read it there, then come back: the tutor in the margin has read it and will answer questions, and the questions below check what stayed.